2026 · journal
Vision Is Not Overhead: One-Pass Block Drafting for Lossless Speculative Decoding in Vision-Language Models
Jungseob Lee, Seongtae Hong, Dongyub Jude Lee, Chanjun Park, Jaehyung Seo, Sugyeong Eo, Heuiseok Lim†
arXiv preprint arXiv:2609.00355
Abstract
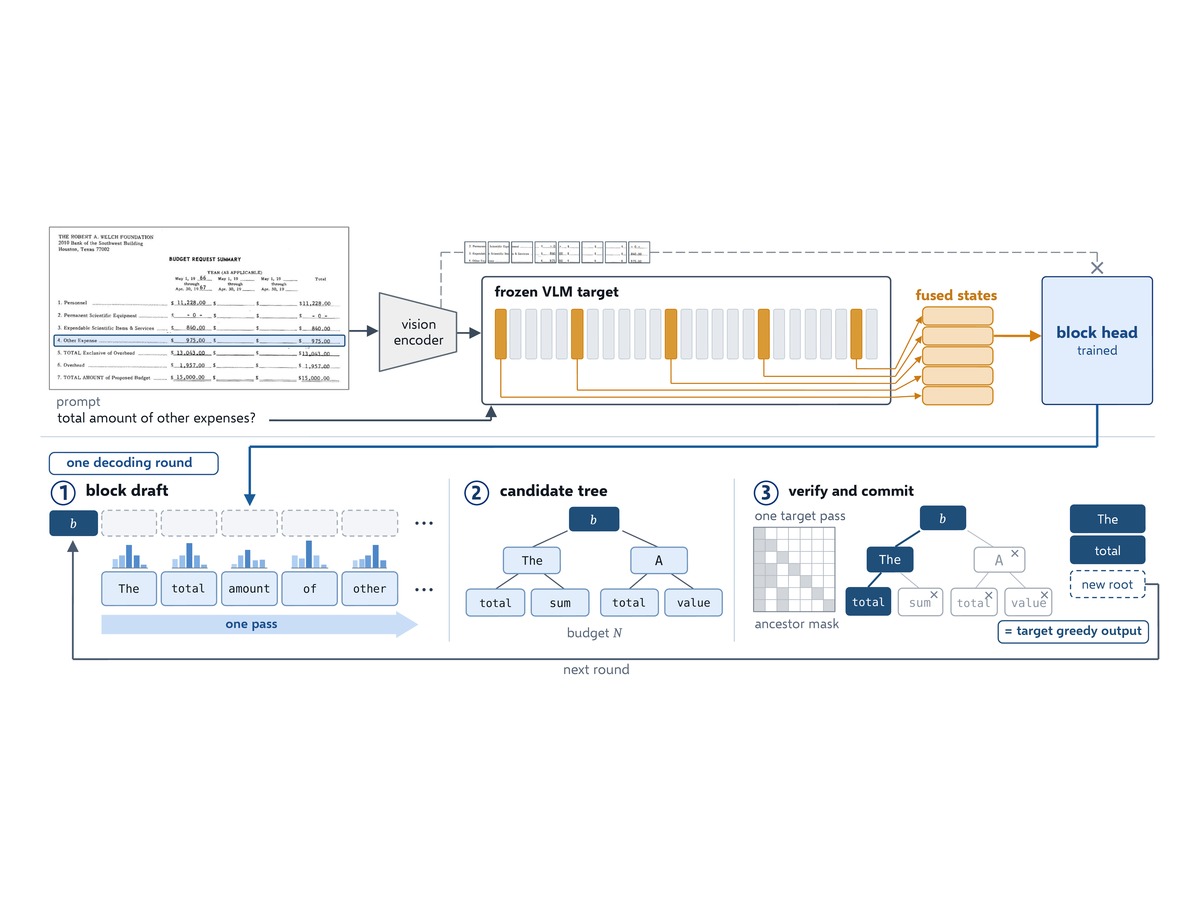
Speculative decoding accelerates generation without changing its output, but on vision-language models (VLMs) a self-reinforcing cycle holds it back. Because an autoregressive drafter pays a sequential pass for each drafted token, it must stay small and can ill afford to attend to the image at each pass. Prior work therefore compresses or hides the image, leaving the drafter weakest on the text the image determines. We present GLANCE, a one-pass block drafter that breaks this cycle on an unmodified VLM target. Its block-diffusion head drafts a whole block in one forward pass over the target's already fused vision-language states, reading the multimodal context once, however deep the draft. The target verifies a wide candidate tree in one pass and commits exactly its greedy output. In one production engine at a fixed round budget, GLANCE decodes up to 3.05 times faster than autoregressive decoding and outpaces the production EAGLE3-VL head on average and by about 11% on grounded tasks. An entropy law explains when drafting pays, predicting the longest accepted blocks on grounded tasks, where the target's next-token entropy is lowest. Our code is available at https://github.com/js-lee-AI/GLANCE.
Motivation
This work treats visual context as useful drafting information rather than overhead, allowing a vision-language model to draft a full token block in one pass while preserving lossless target-model generation.
Resources
BibTeX
@article{2026-vision-not-overhead-one-pass-block-drafting,
  title = {Vision Is Not Overhead: One-Pass Block Drafting for Lossless Speculative Decoding in Vision-Language Models},
  author = {Jungseob Lee and Seongtae Hong and Dongyub Jude Lee and Chanjun Park and Jaehyung Seo and Sugyeong Eo and Heuiseok Lim},
  journal = {arXiv preprint arXiv:2609.00355},
  year = {2026},
  month = {9},
  abstract = {Speculative decoding accelerates generation without changing its output, but on vision-language models (VLMs) a self-reinforcing cycle holds it back. Because an autoregressive drafter pays a sequential pass for each drafted token, it must stay small and can ill afford to attend to the image at each pass. Prior work therefore compresses or hides the image, leaving the drafter weakest on the text the image determines. We present GLANCE, a one-pass block drafter that breaks this cycle on an unmodified VLM target. Its block-diffusion head drafts a whole block in one forward pass over the target's already fused vision-language states, reading the multimodal context once, however deep the draft. The target verifies a wide candidate tree in one pass and commits exactly its greedy output. In one production engine at a fixed round budget, GLANCE decodes up to 3.05 times faster than autoregressive decoding and outpaces the production EAGLE3-VL head on average and by about 11% on grounded tasks. An entropy law explains when drafting pays, predicting the longest accepted blocks on grounded tasks, where the target's next-token entropy is lowest. Our code is available at https://github.com/js-lee-AI/GLANCE.},
  url = {https://arxiv.org/abs/2609.00355},
  doi = {10.48550/arXiv.2609.00355}
}