2026 · conference
Improving korean-english cross-lingual retrieval: A data-centric study of language composition and model merging
Youngjoon Jang, Junyoung Son, Taemin Lee, Seongtae Hong, Hyeonseok Moon, Seungyoon Lee, Andrew Matteson, Heuiseok Lim†
Proceedings of the 1st Workshop on Multilinguality in the Era of Large Language Models (MeLLM 2026)
Abstract
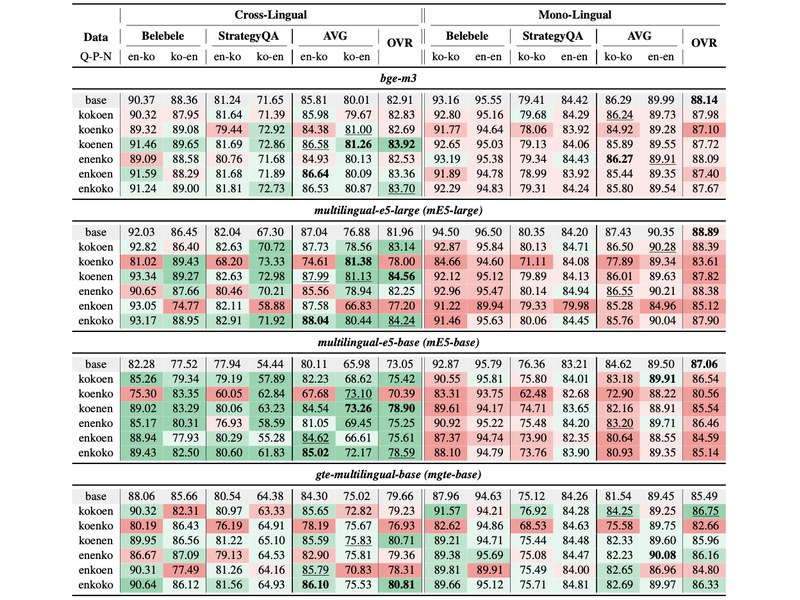
With the increasing utilization of multilingual text information, Cross-Lingual Information Retrieval (CLIR) has become a crucial research area. However, the impact of training data composition on CLIR and Mono-Lingual Information Retrieval (Mono-IR) performance remains underexplored. To investigate this data-centric aspect, we construct linguistically parallel Korean-English datasets and train multilingual retrieval models with various language combinations. Our experiments reveal that the language composition of training data significantly influence IR performance, exhibiting important inter-lingual correlations: Using specific language pairs improves CLIR performance, while declines Mono-IR performance. Our work demonstrates that simple weight-averaged model merging can effectively mitigate this trade-off, achieving strong CLIR results while preserving Mono-IR capabilities. Our findings highlight the effects of linguistic configuration of training data on both CLIR and Mono-IR, and present model merging as a viable strategy to optimize performance across these tasks.
Motivation
<!-- Replace the sentence below with your personal motivation for this work. -->Personal motivation for this work will be added here.
Notes
<!-- Optional: add contributions, behind-the-scenes notes, talks, code, or media links. -->BibTeX
@inproceedings{2026-improving-korean-english-cross-lingual-retrieval,
  title = {Improving korean-english cross-lingual retrieval: A data-centric study of language composition and model merging},
  author = {Youngjoon Jang and Junyoung Son and Taemin Lee and Seongtae Hong and Hyeonseok Moon and Seungyoon Lee and Andrew Matteson and Heuiseok Lim},
  booktitle = {Proceedings of the 1st Workshop on Multilinguality in the Era of Large Language Models (MeLLM 2026)},
  year = {2026},
  month = {7},
  pages = {30-43},
  abstract = {With the increasing utilization of multilingual text information, Cross-Lingual Information Retrieval (CLIR) has become a crucial research area. However, the impact of training data composition on CLIR and Mono-Lingual Information Retrieval (Mono-IR) performance remains underexplored. To investigate this data-centric aspect, we construct linguistically parallel Korean-English datasets and train multilingual retrieval models with various language combinations. Our experiments reveal that the language composition of training data significantly influence IR performance, exhibiting important inter-lingual correlations: Using specific language pairs improves CLIR performance, while declines Mono-IR performance. Our work demonstrates that simple weight-averaged model merging can effectively mitigate this trade-off, achieving strong CLIR results while preserving Mono-IR capabilities. Our findings highlight the effects of linguistic configuration of training data on both CLIR and Mono-IR, and present model merging as a viable strategy to optimize performance across these tasks.},
  url = {https://aclanthology.org/2026.mellm-1.3/}
}