2026 · conference
CLEAR: Cross-Lingual Enhancement in Retrieval via Reverse-training
Seungyoon Lee, Minhyuk Kim, Seongtae Hong, Youngjoon Jang, Dongsuk Oh, Heuiseok Lim†
Proceedings of the 64th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers)
Abstract
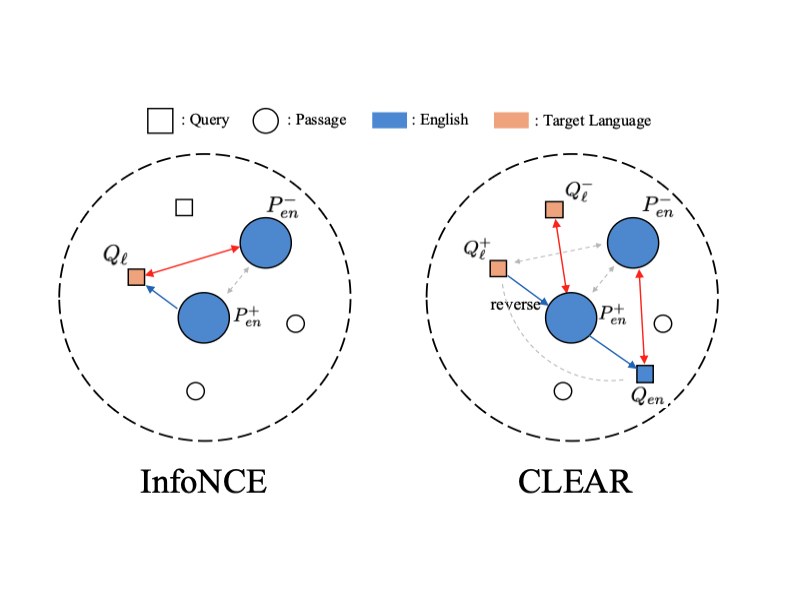
Existing multilingual embedding models often encounter challenges in cross-lingual scenarios due to imbalanced linguistic resources and less consideration of cross-lingual alignment during training. Although standardized contrastive learning approaches for cross-lingual adaptation are widely adopted, they may struggle to capture fundamental alignment between languages and degrade performance in well-aligned languages such as English. To address these challenges, we propose Cross-Lingual Enhancement in RetrievAl via Reverse-training (CLEAR), a novel loss function utilizing a reverse training scheme to improve retrieval performance across diverse cross-lingual retrieval scenarios. CLEAR leverages an English passage as a bridge to strengthen alignments between the target language and English, ensuring robust performance in the cross-lingual retrieval task. Our extensive experiments demonstrate that CLEAR achieves notable improvements in cross-lingual scenarios, with gains up to 15%, particularly in low-resource languages, while minimizing performance degradation in English. Furthermore, our findings highlight that CLEAR offers promising effectiveness even in multilingual training, suggesting its potential for broad application and scalability. We release the code at https://github. com/dltmddbs100/CLEAR.
Motivation
<!-- Replace the sentence below with your personal motivation for this work. -->Personal motivation for this work will be added here.
Notes
<!-- Optional: add contributions, behind-the-scenes notes, talks, code, or media links. -->BibTeX
@inproceedings{2026-clear-cross-lingual-enhancement-retrieval-reverse,
  title = {CLEAR: Cross-Lingual Enhancement in Retrieval via Reverse-training},
  author = {Seungyoon Lee and Minhyuk Kim and Seongtae Hong and Youngjoon Jang and Dongsuk Oh and Heuiseok Lim},
  booktitle = {Proceedings of the 64th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers)},
  year = {2026},
  month = {7},
  pages = {347-362},
  abstract = {Existing multilingual embedding models often encounter challenges in cross-lingual scenarios due to imbalanced linguistic resources and less consideration of cross-lingual alignment during training. Although standardized contrastive learning approaches for cross-lingual adaptation are widely adopted, they may struggle to capture fundamental alignment between languages and degrade performance in well-aligned languages such as English. To address these challenges, we propose Cross-Lingual Enhancement in RetrievAl via Reverse-training (CLEAR), a novel loss function utilizing a reverse training scheme to improve retrieval performance across diverse cross-lingual retrieval scenarios. CLEAR leverages an English passage as a bridge to strengthen alignments between the target language and English, ensuring robust performance in the cross-lingual retrieval task. Our extensive experiments demonstrate that CLEAR achieves notable improvements in cross-lingual scenarios, with gains up to 15%, particularly in low-resource languages, while minimizing performance degradation in English. Furthermore, our findings highlight that CLEAR offers promising effectiveness even in multilingual training, suggesting its potential for broad application and scalability. We release the code at https://github. com/dltmddbs100/CLEAR.},
  url = {https://aclanthology.org/2026.acl-long.13/}
}