2026 · conference
Beyond Hard Negatives: The Importance of Score Distribution in Knowledge Distillation
Youngjoon Jang, Seongtae Hong, Hyeonseok Moon, Heuiseok Lim†
Proceedings of the 49th International ACM SIGIR Conference on Research and Development in Information Retrieval
Abstract
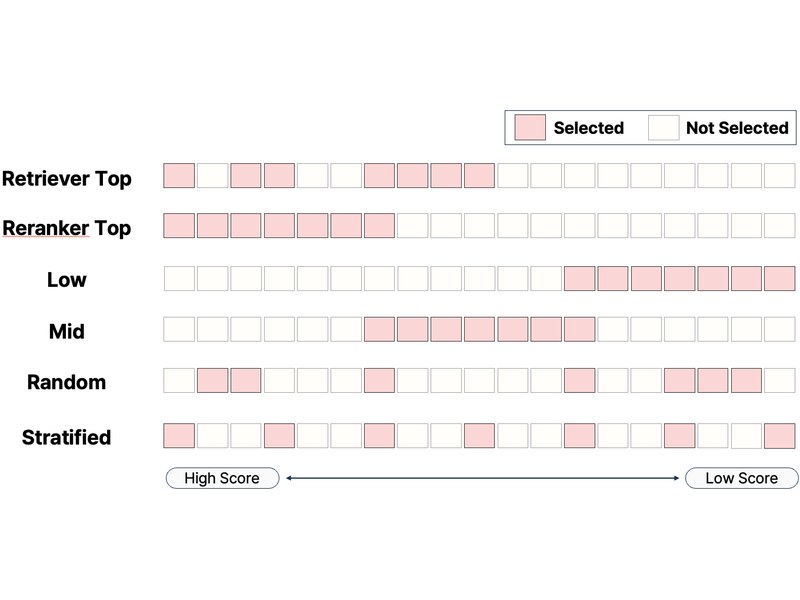
Transferring knowledge from a cross-encoder teacher via Knowledge Distillation (KD) has become a standard paradigm for training retrieval models. While existing studies have largely focused on mining hard negatives to improve discrimination, the systematic composition of training data and the resulting teacher score distribution have received relatively less attention. In this work, we highlight that focusing solely on hard negatives prevents the student from learning the comprehensive preference structure of the teacher, potentially hampering generalization. To effectively emulate the teacher score distribution, we propose a Stratified Sampling strategy that uniformly covers the entire score spectrum. Experiments on in-domain and out-of-domain benchmarks confirm that Stratified Sampling, which preserves the variance and entropy of teacher scores, serves as a robust baseline, significantly outperforming top-K …
Motivation
<!-- Replace the sentence below with your personal motivation for this work. -->Personal motivation for this work will be added here.
Notes
<!-- Optional: add contributions, behind-the-scenes notes, talks, code, or media links. -->BibTeX
@inproceedings{2026-beyond-hard-negatives-importance-score-distribution,
  title = {Beyond Hard Negatives: The Importance of Score Distribution in Knowledge Distillation},
  author = {Youngjoon Jang and Seongtae Hong and Hyeonseok Moon and Heuiseok Lim},
  booktitle = {Proceedings of the 49th International ACM SIGIR Conference on Research and Development in Information Retrieval},
  year = {2026},
  month = {7},
  pages = {3811-3816},
  abstract = {Transferring knowledge from a cross-encoder teacher via Knowledge Distillation (KD) has become a standard paradigm for training retrieval models. While existing studies have largely focused on mining hard negatives to improve discrimination, the systematic composition of training data and the resulting teacher score distribution have received relatively less attention. In this work, we highlight that focusing solely on hard negatives prevents the student from learning the comprehensive preference structure of the teacher, potentially hampering generalization. To effectively emulate the teacher score distribution, we propose a Stratified Sampling strategy that uniformly covers the entire score spectrum. Experiments on in-domain and out-of-domain benchmarks confirm that Stratified Sampling, which preserves the variance and entropy of teacher scores, serves as a robust baseline, significantly outperforming top-K …},
  url = {https://dl.acm.org/doi/abs/10.1145/3805712.3809843}
}